All You Need to Know about Gene Expression Omnibus (GEO)

Kriti Srivastava

October 23, 2026

In a Nutshell: The Gene Expression Omnibus (GEO) is NCBI's public archive of functional genomics data like microarray, bulk and single-cell RNA-seq, ChIP-seq, methylation and more. You can search it through GEO DataSets or the Advanced Search Builder, and download through the GEO FTP site, GEOquery or the SRA. Access is the easy part. The hard part is that every study describes its samples in its own words, so datasets cannot be compared until their metadata is mapped to a shared vocabulary. That mapping, done one project at a time, is the work that Elucidata does.
This guide covers how GEO is organized, what it holds, how to search and download it, and why reusing its data across studies takes more than a download script.
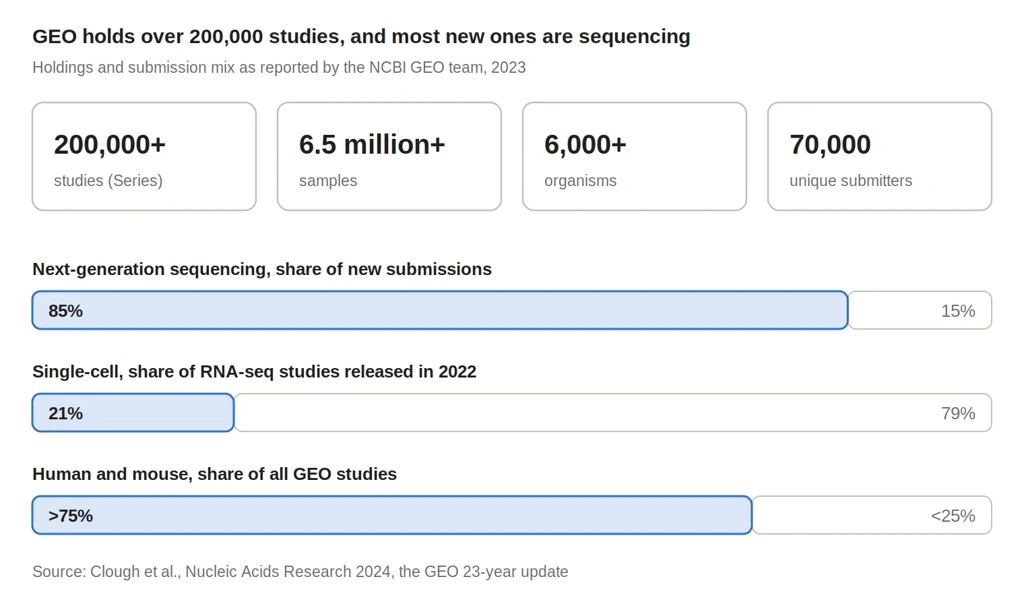
GEO is an international public repository, run by NCBI since 2000, that archives and freely distributes high-throughput gene expression and other functional genomics data. It began with microarrays and now accepts sequencing-based studies of expression, methylation, chromatin structure and protein-DNA binding. Submitters provide raw data, processed data and descriptive metadata under community reporting standards.
Everything in GEO hangs off four record types. Knowing them saves time, because most tools ask for an accession of one specific type.
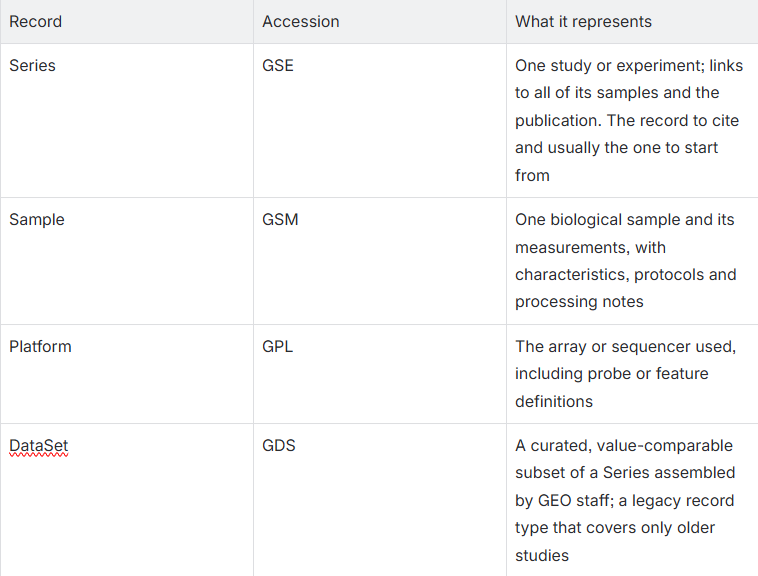
A Series can contain samples run on more than one platform, and a sample can belong to more than one Series. Both details matter when you assemble a cohort from several studies.
GEO is organized around experiment types rather than file formats. The main ones are gene expression and non-coding RNA profiling, chromatin immunoprecipitation (ChIP-seq and ChIP-chip), genome methylation profiling, genome variation profiling by array, SNP arrays, high-throughput RT-PCR, SAGE and protein arrays, each by microarray or sequencing where both apply.
Two newer groups now account for much of the growth. Single-cell RNA-seq studies are filed as expression profiling by high-throughput sequencing, usually with count matrices in supplementary files, so a type filter alone will not isolate them. Spatial transcriptomics studies follow the same pattern. Both carry far richer metadata needs than bulk studies, because cell types, not just samples, have to be labeled.
GEO also spans many organisms: human and mouse dominate, followed by rat, model organisms, plants and microbes.
GEO DataSets is the main search interface for Series and Samples; GEO Profiles searches individual gene expression profiles within curated DataSets. Both sit in NCBI's Entrez system, so keyword search works, but field tags are what make results usable. The Advanced Search Builder, linked from the top of each search page, builds tagged queries for you.
The tags practitioners use most are organism [ORGN], entry type [ETYP] (gse, gsm, gpl or gds), study type [DataSet Type] and publication date [PDAT]. Two examples:
liver AND "Mus musculus"[ORGN] AND gse[ETYP] AND "expression profiling by high throughput sequencing"[DataSet Type] AND 2020:2026[PDAT]
("single cell" OR scRNA-seq) AND "Homo sapiens"[ORGN] AND gse[ETYP] AND ("ulcerative colitis" OR "Crohn disease")
The first returns mouse liver bulk RNA-seq Series from 2020 onward. The second is a first pass at human single-cell IBD studies. Neither tells you whether a study has the controls, timepoints or treatment arms your analysis needs. Keyword search matches words in titles and summaries; it cannot read the sample-level details that decide fit. That limit is the subject of the section on reuse below.
Every Series page lists what the submitter uploaded: the series matrix, SOFT and MINiML metadata files, and supplementary files such as count tables or single-cell matrices. Sequencing studies link to the Sequence Read Archive (SRA) for raw reads. GEO2R offers quick differential expression on many microarray and some RNA-seq Series, and lets you export the result. Processed files are whatever the authors chose to share, in whatever format they chose, so check each study before you build a pipeline around it.
Most teams skip the browser after the first few studies. These are the tools practitioners actually use.
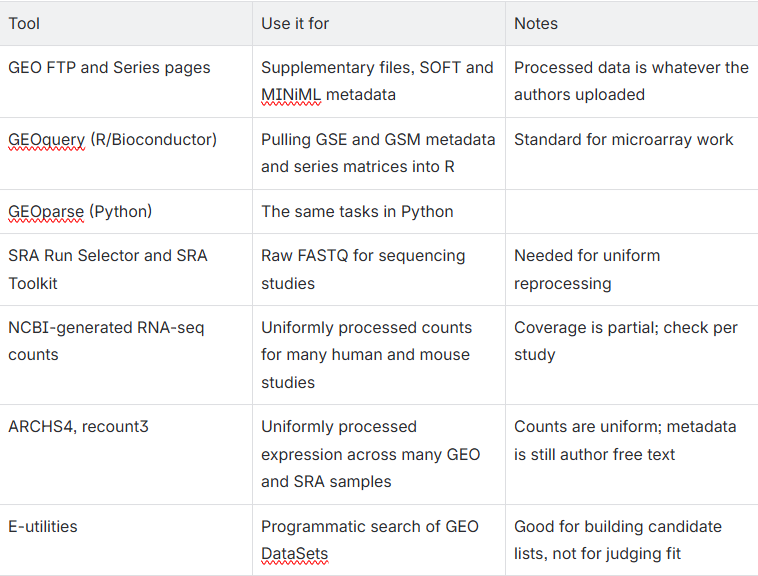
Notice the pattern in the last column. Tools now solve uniform processing well. None of them solve metadata.
GEO solved data deposition. It did not solve comparability. Each submitter describes samples in their own vocabulary, so the same concept arrives in a dozen forms. One study records tissue as "liver", another as "liver biopsy, segment IV", and a third leaves the field blank and names the tissue only in its methods. Controls are "healthy" in one study and "non-tumor adjacent" in the next.
None of these records is wrong. They simply cannot sit side by side until each value is mapped to a shared ontology: UBERON for anatomy, MONDO for disease, the Cell Ontology for cell types and Cellosaurus for cell lines. Most pharma teams then map onward to their own internal vocabulary, so public data lands in the same model as their proprietary data.
The evidence is also rarely where you would look for it. Take GSM3178782, a sample in the public human liver atlas GSE115469.
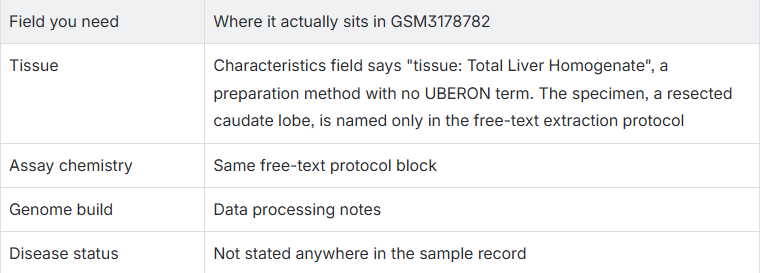
Three of four answers sit outside the structured fields, and this is a well-run study. Multiply that by hundreds of studies and the real bottleneck appears. Curating one single-cell dataset by hand takes a skilled curator about a week, which is why many analyses use 10 studies when 200 are available.
Have a question GEO should be able to answer? Send Elucidata your inclusion and exclusion criteria. You get back a ranked shortlist of GEO and ArrayExpress datasets, and a plan to bring them into your vocabulary. Get a ranked GEO shortlist (- Link Book a demo)
Around 2020, Elucidata set out to clean GEO for everyone at once. Across hundreds of thousands of studies, the team could not hold the quality thresholds it had promised, and it said so. The model changed. Elucidata now curates the datasets a specific question needs, to the vocabulary that team uses, and holds each delivery to agreed accuracy targets.
So if you are looking for a pre-annotated copy of GEO, Elucidata does not sell one, and you should be cautious of anyone who does. A generic annotation of all of GEO is mapped to someone else's model. You would still need to re-map it to yours, and you would inherit errors you cannot see.
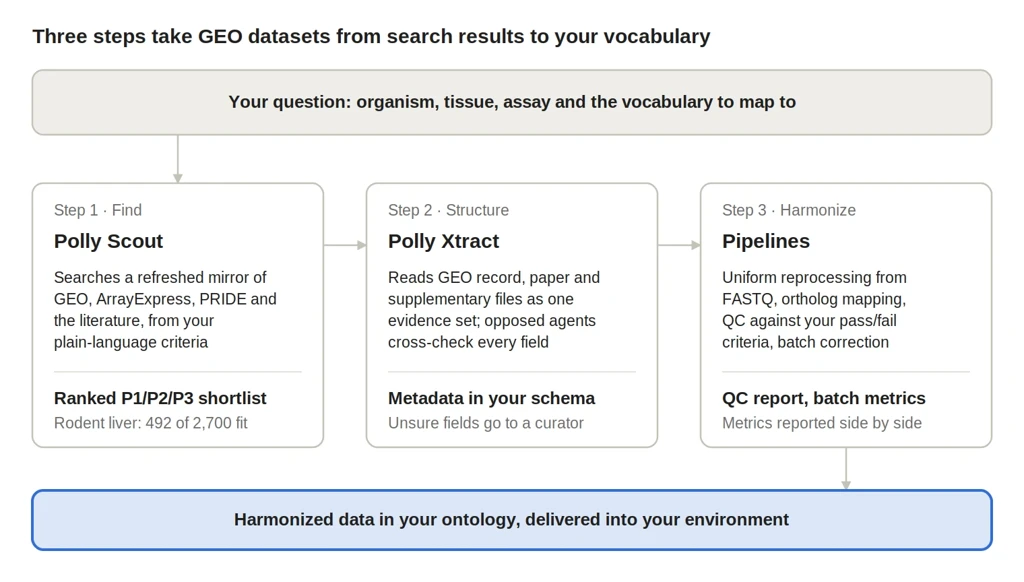
Elucidata's approach runs in three steps, each handled by a dedicated component and each with a result you can check.
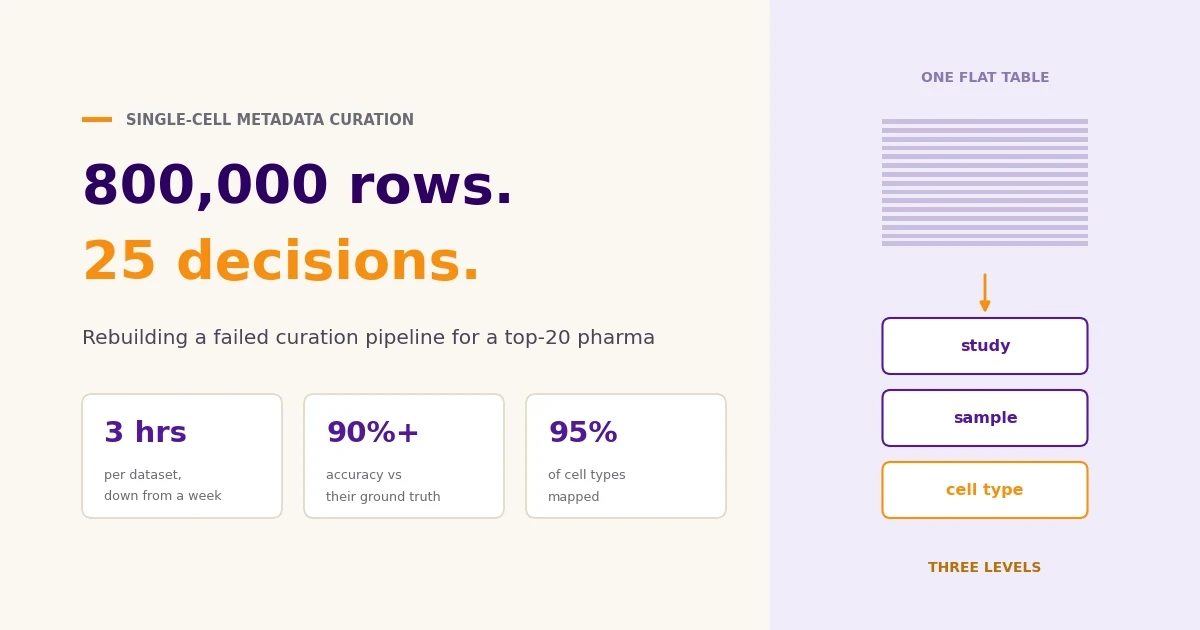
At a top-20 pharma, this approach exceeded 90% metadata accuracy against the client's own independently dual-curated ground truth and mapped 95% of cell types to their internal vocabulary. Hands-on curation for a 200-sample dataset fell from about a week to roughly eight hours. Cell-type accuracy came in at 85% against a 90% target, and low-confidence mappings were routed to review rather than passed silently. Read the full case study.
Whether you build in-house or bring in a partner, these questions separate real curation from string matching.
Does Elucidata have a pre-annotated copy of GEO?
No. Elucidata curates the datasets your question needs, to your vocabulary, with agreed accuracy targets. An attempt to curate all of GEO did not meet Elucidata's quality bar, so the company moved to per-project curation.
Can you map GEO metadata to our internal ontology?
Yes, and it is the most common request. Mapping covers public ontologies (UBERON, MONDO, Cell Ontology, Cellosaurus) and continues onward to your internal terms.
How long does a GEO harmonization project take?
It depends on dataset count and modality. A recent public single-cell harmonization project for a top pharma team was delivered in about three months, including integration into the client's internal database.
Do we have to use your platform?
No. Harmonized data can be delivered into your environment, or your team can use Polly Scout and Polly Xtract directly.
Which repositories besides GEO do you cover?
ArrayExpress, SRA, PRIDE, GDC and PDC, and the literature through PubMed Central, depending on modality.
Cite the Series accession (GSExxx), because that record summarizes the experiment and links to every sample and file. A typical data citation gives the authors, year, dataset title, "Gene Expression Omnibus", the accession and its URL, for example: Smith AB, Johnson CD (2022). Gene expression profiling of human liver samples. Gene Expression Omnibus, GSE12345. If you harmonized samples from several Series, list every accession you used, ideally in a supplementary table.
Tell Elucidata the question and the samples you need. You will get back a ranked shortlist of GEO and ArrayExpress datasets, and a plan to bring them into your vocabulary.
Send your criteria & get a ranked GEO shortlist.
Want to explore more? Read the latest work we did with one of the top 10 pharma company on single-cell metadata curation and GEO data harmonization here