.webp)


.webp)

.webp)


.webp)

.webp)


.webp)


.webp)

.webp)


.webp)

.webp)


.webp)


.webp)

.webp)


.webp)

.webp)


.webp)


.webp)

.webp)


.webp)

.webp)


With Xtract running, your documents, clinical, omics, and regulatory data becomes an AI-ready asset.
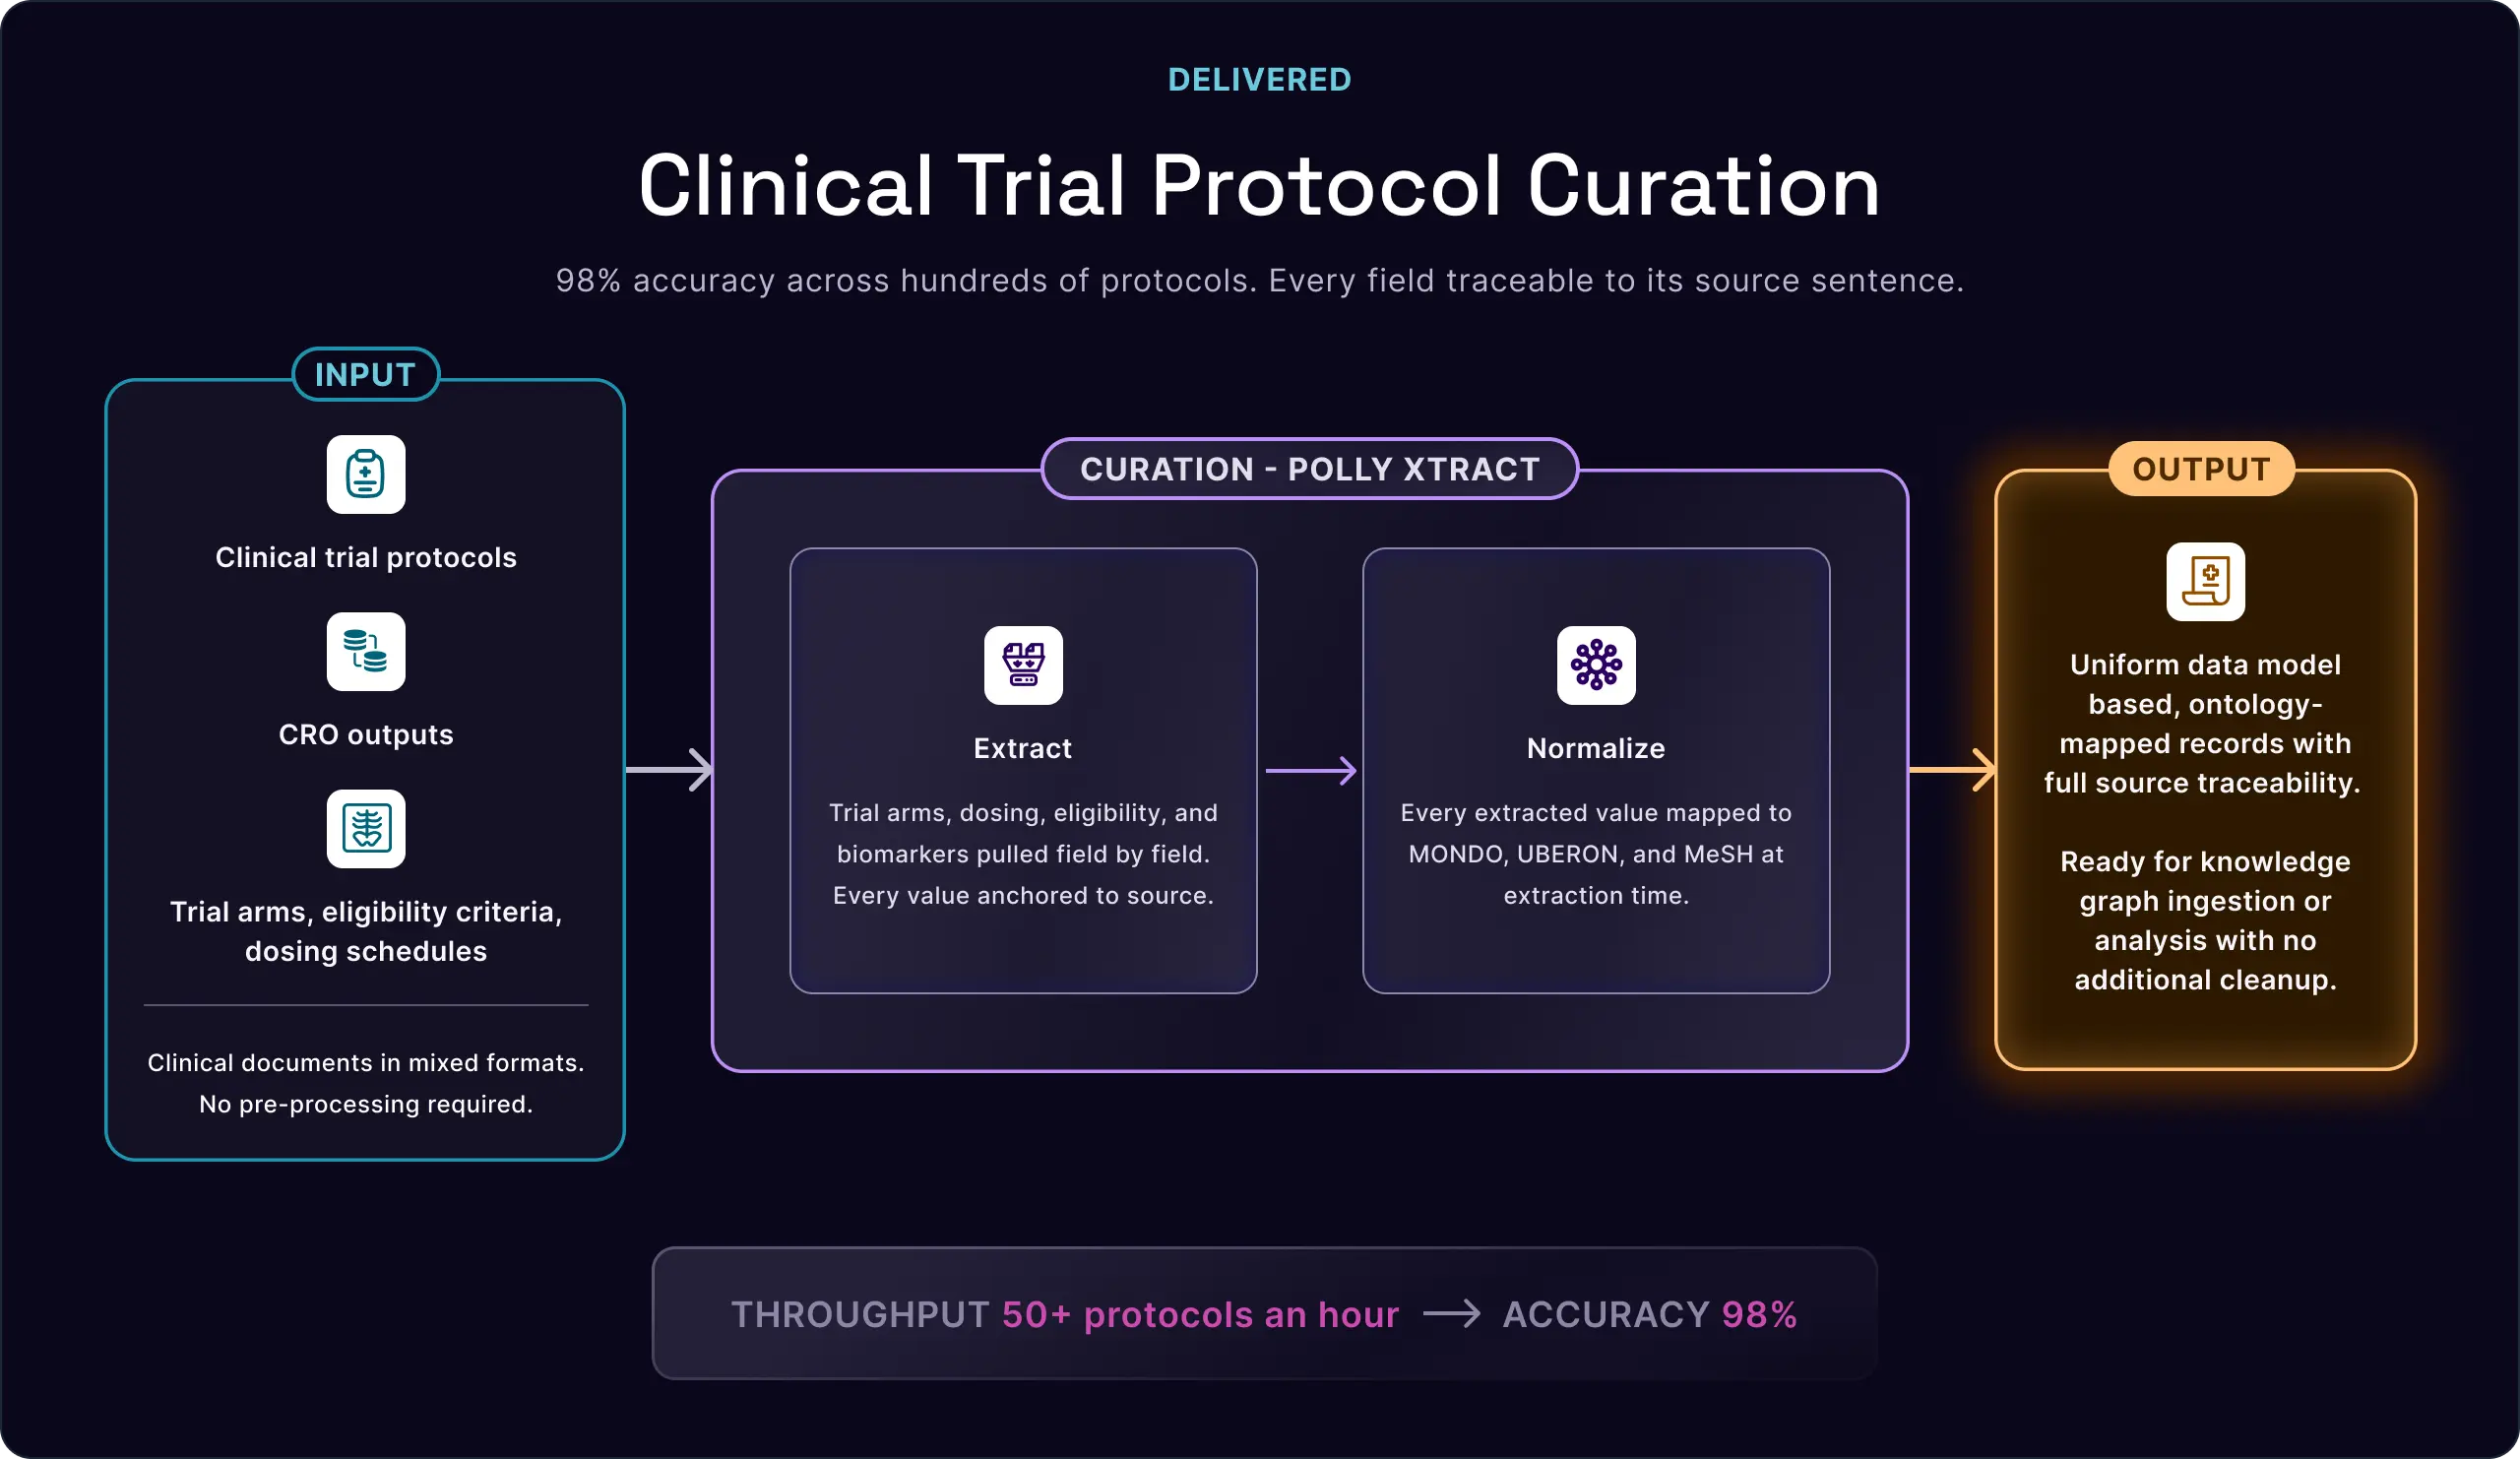
Endpoints, eligibility criteria, dosing arms, and biomarkers extracted from hundreds of reports, structured for target identification without manual reading.
Every extracted value mapped to your schema and normalized to any specific ontology, such as MONDO, UBERON, and MeSH.
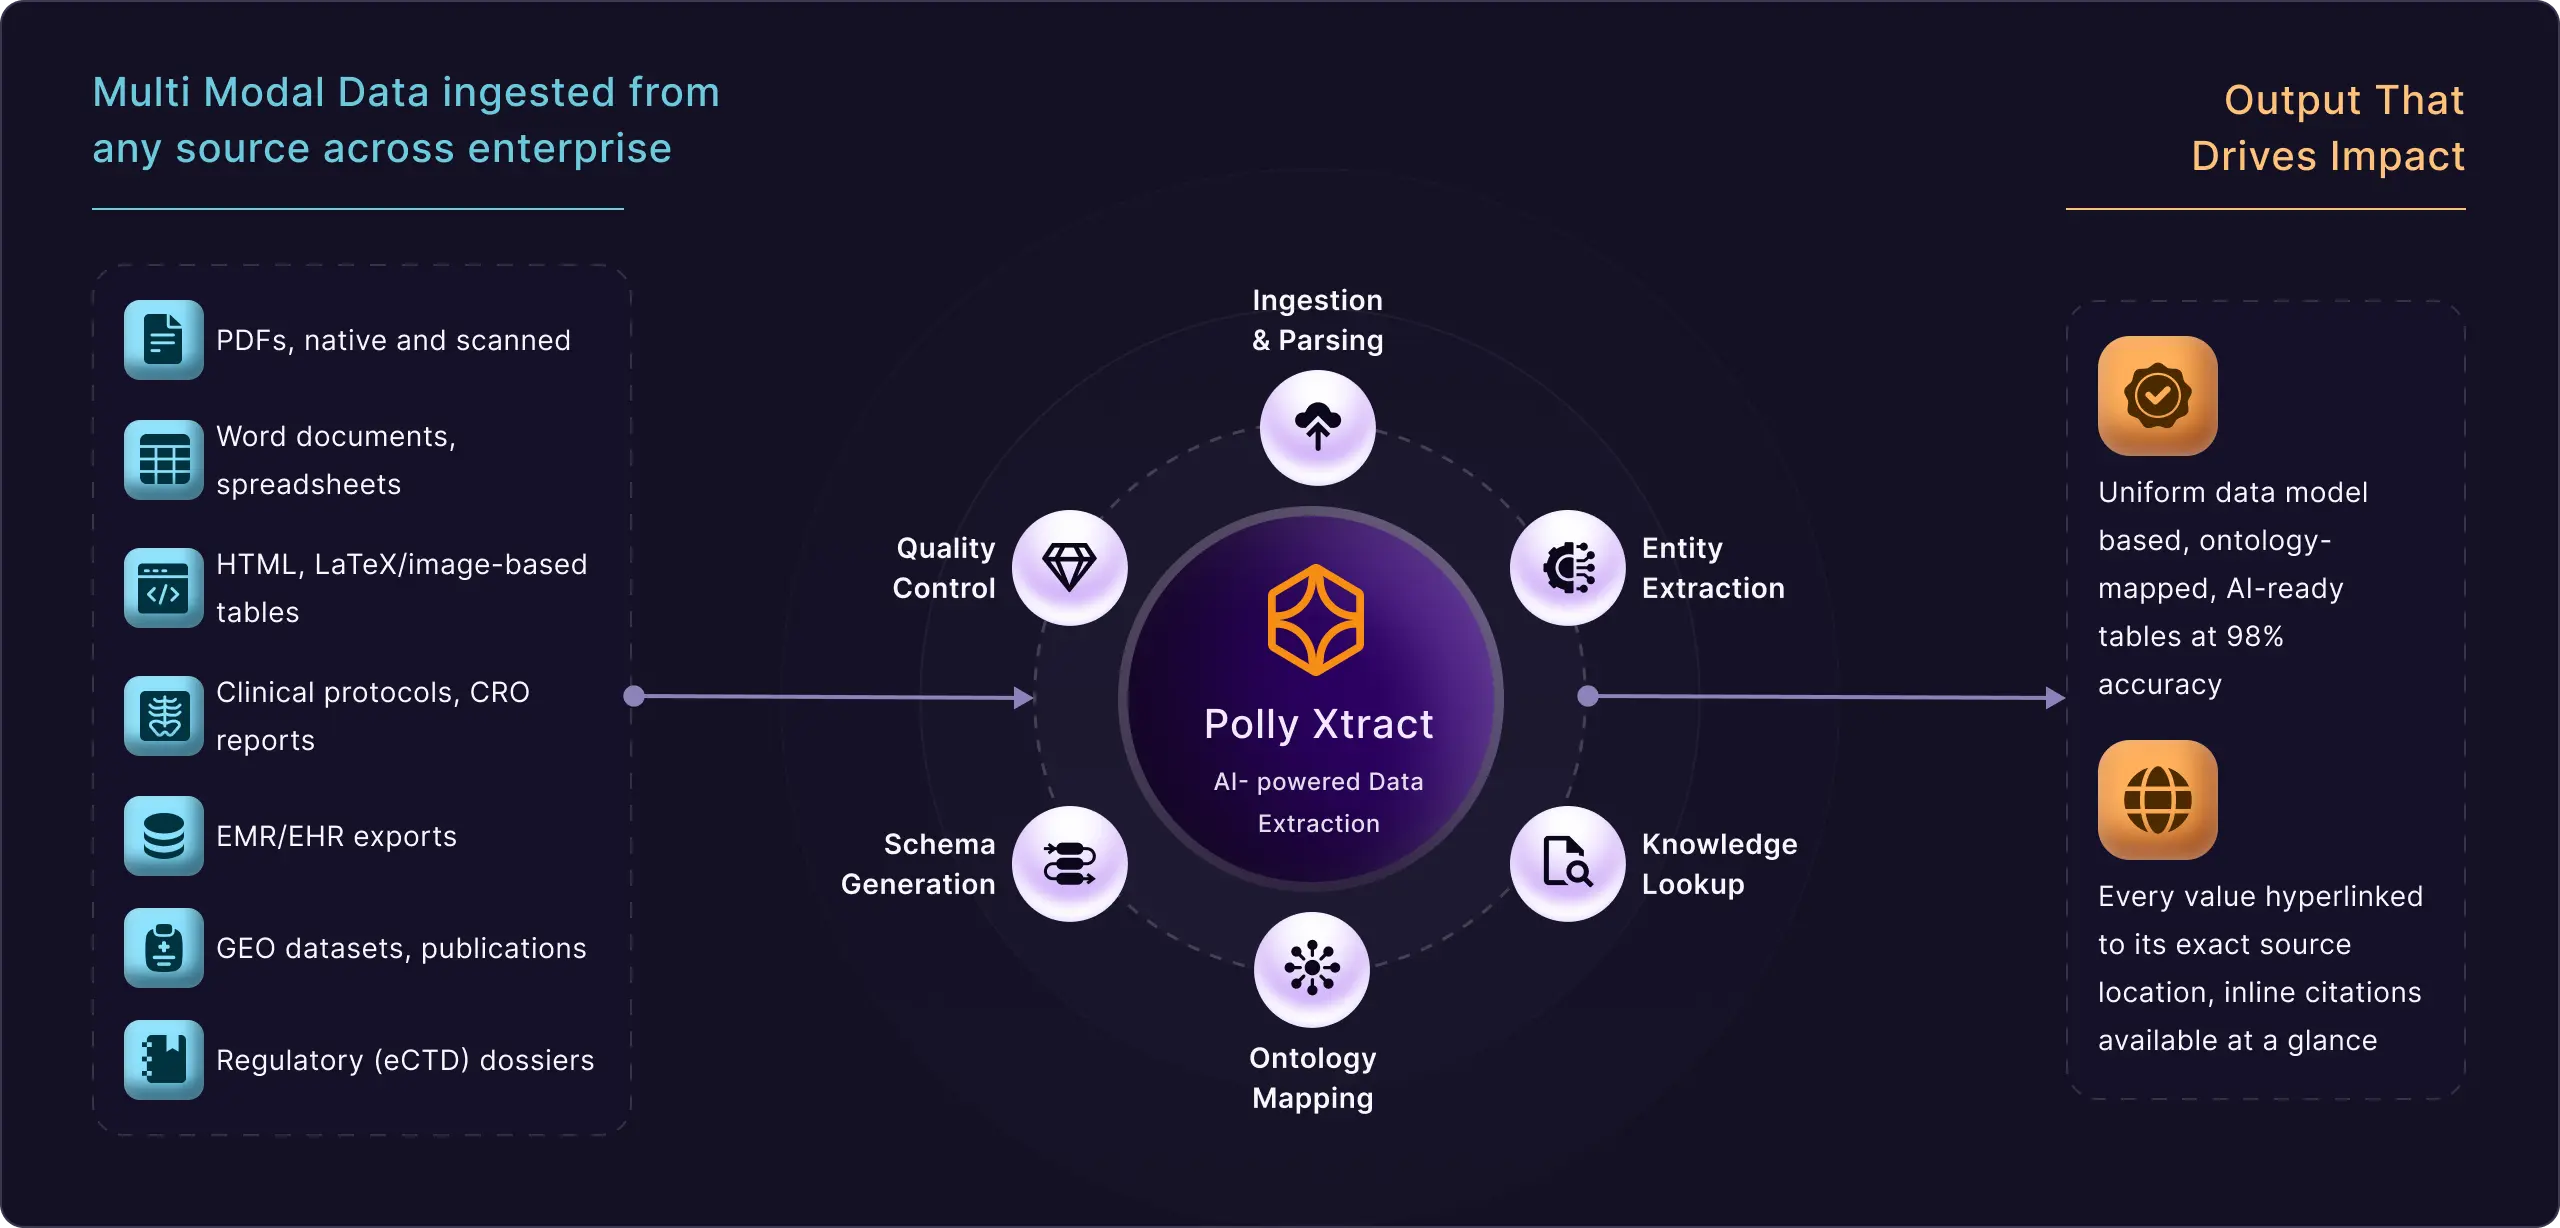
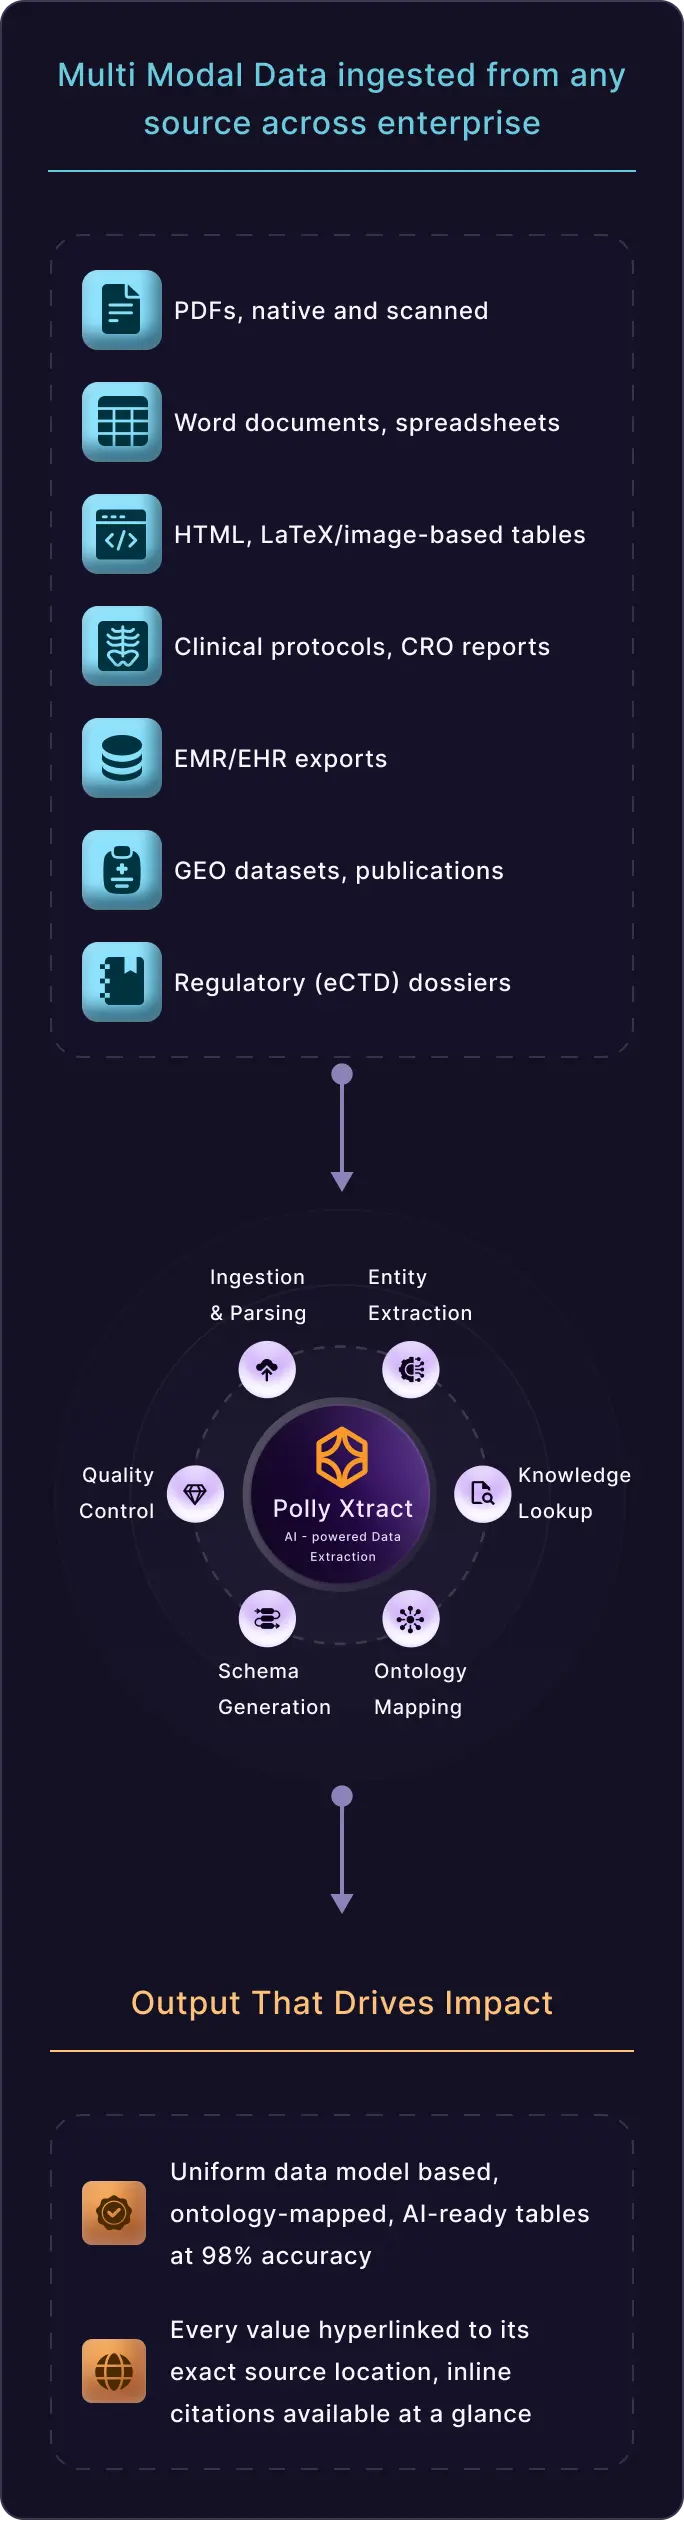
Every field hyperlinks to its source sentence, so a reviewer can open the original document text behind any number, making it 4x faster with human level quality.
Documents go in structured, schema-enforced, and evidence-linked. You review the flagged fields.
.webp)
.webp)
Xtract powers the curation layer across four of Elucidata's partnership models.
Xtract structures your proprietary documents, CRO reports, assay data, and trial protocols for ingestion into the program-specific knowledge graph, at 98% field-level accuracy, with full audit trails carried through to the validation stage.
Xtract is the extraction layer ahead of harmonization, turning unstructured documents, including patient-level EMR/EHR exports, into schema-enforced records before they enter the harmonization pipeline.
When Elucidata owns a customer's computational infrastructure layer, Xtract is the extraction step underneath it, turning unstructured proprietary documents into schema-enforced records the rest of that infrastructure runs on.
Building a multi-omic and clinical profile of a patient subgroup, one of the translational offerings under this partnership, starts with Xtract pulling structured values out of the unstructured clinical sources behind that population's records, ahead of cohort profiling.
We integrate Xtract into your document pipeline in the model that fits your program.
Web interface for document upload, schema management, extraction review, and structured data export.
We route Xtract outputs directly into your downstream systems, LIMS, data lakes, and knowledge graph pipelines, by API or delivery handoff.
Full API documentation and integration guides available on request.
PDFs (native and scanned), Word, spreadsheets, HTML and LaTeX-based tables, CRO reports, EMR/EHR exports, and clinical protocols. No pre-processing required.
A general-purpose LLM loses context in long documents and returns no confidence signal. Xtract runs six agents, parsing, entity extraction, knowledge lookup, ontology mapping, schema generation, and quality control, each built for one step of schema-enforced curation at scale, with a human review loop for anything flagged.
What accuracy benchmarks does Xtract achieve? 98% accuracy, matching or exceeding human-expert benchmarks, with 100% consistency across binary fields over repeated runs and 90% groundedness, meaning extracted values trace back to source. Across a 50+ field benchmark spanning study design, trial arms, and outcomes, accuracy runs at 90%+ for binary and textual fields and roughly 87% for numeric fields, with F1 scores above 85% across most field types.
Both partnership models. In Program Partner engagements, Xtract structures proprietary documents for knowledge graph ingestion, from nomination through validation. In Data & Harmonization Partner engagements, it's the extraction layer that turns unstructured and patient-level documents into schema-enforced records ahead of harmonization.
Xtract turns unstructured documents, CRO reports, protocols, publication supplements, into structured records ready for knowledge graph ingestion, with every value traceable to its source.
Yes. Internal assay reports, LIMS exports, and regulatory submissions go through the same pipeline as public sources.